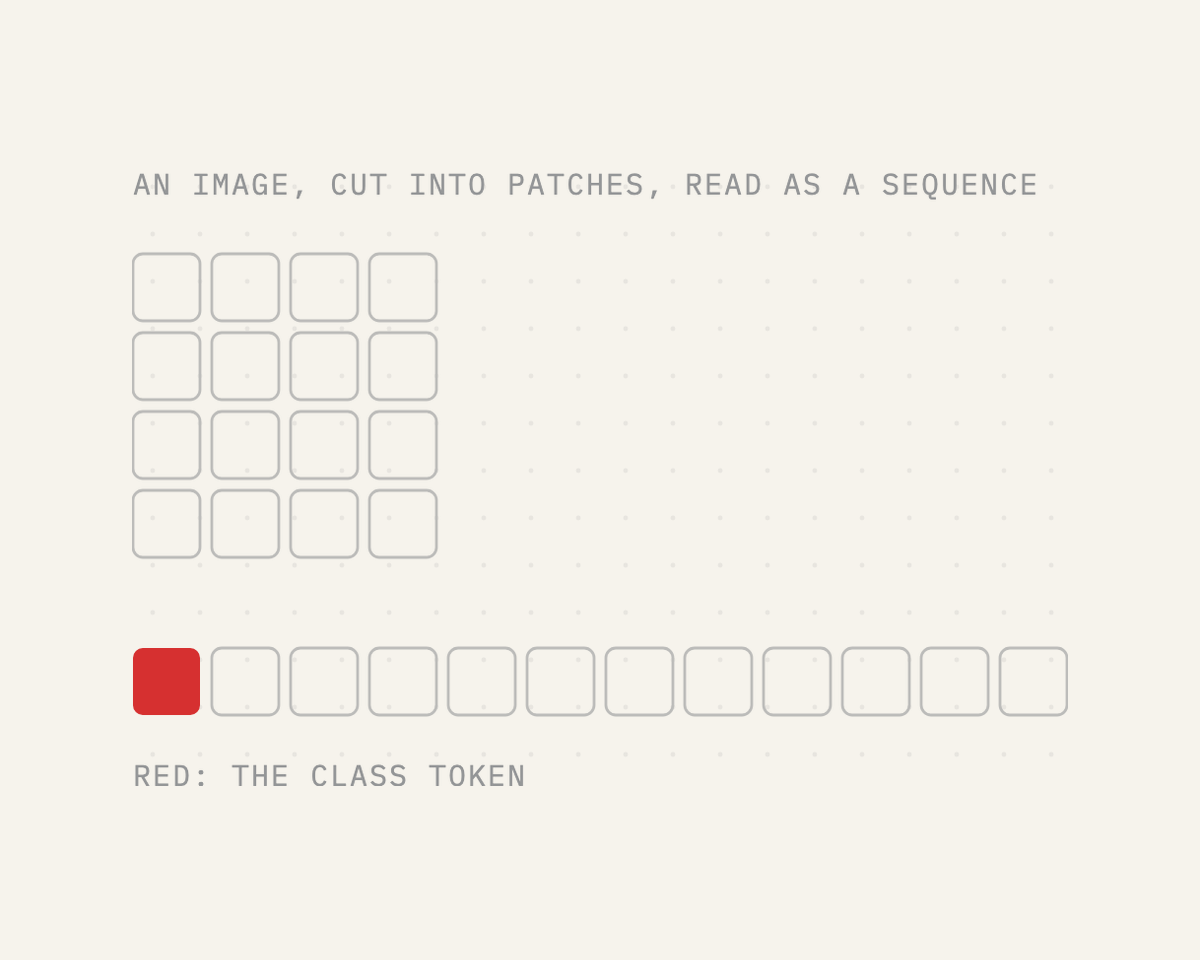
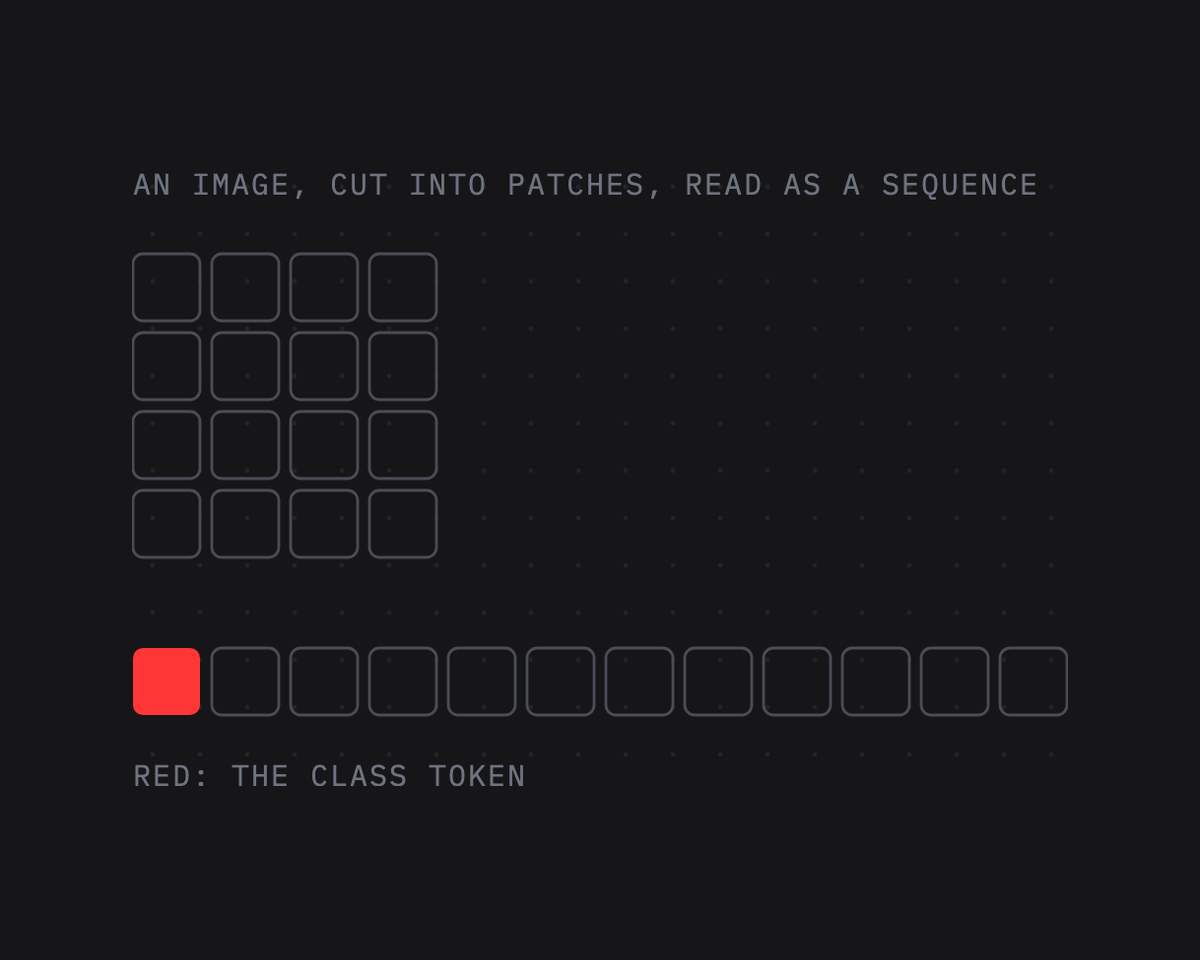
The Vision Transformer reads images as sequences of patches
How a Transformer reads a photo: every step from pixels to a sequence of 197 vectors on a real image, written from scratch and checked against Google's ViT-B/16. What the model learned about patches and positions, where its heads look, DINO's heads finding objects without labels, and ViT against a CNN on satellite images when labels are scarce.